The fastest way to improve at distributed system whiteboards may be to draw less at first. Spend the opening minutes asking questions, setting scope, and naming the main constraint before you sketch a box.
Then build skill in layers: requirements, architecture, one primitive at a time, failure handling, and timed mock sessions. This method helps you explain your thinking instead of reciting system design terms.
We reviewed 5 widely read system design whiteboarding guides: HackerNoon, GeeksforGeeks, Formation, DesignGurus, and Exponent. 4 of the 5 tell readers to gather requirements before drawing, but none isolates a single primitive for its own drill. Only 1 lays out a failure-mode pass with a decision for each failure, and 2 time-box a mock on unseen prompts. Isolating primitives and pairing each failure with a stated decision remain the rarest steps across these 5 guides.
Table of Contents
- Step 1: Start With Requirements Before Drawing
- Step 2: Draw the Architecture and Narrate Each Decision
- Step 3: Practice One Distributed-System Primitive at a Time
- Step 4: Add Failure Modes, Trade-Offs, and Precise Vocabulary
- Step 5: Run Timed Mock Explanations on Unseen Problems
- FAQ
- Conclusion
Step 1: Start With Requirements Before Drawing
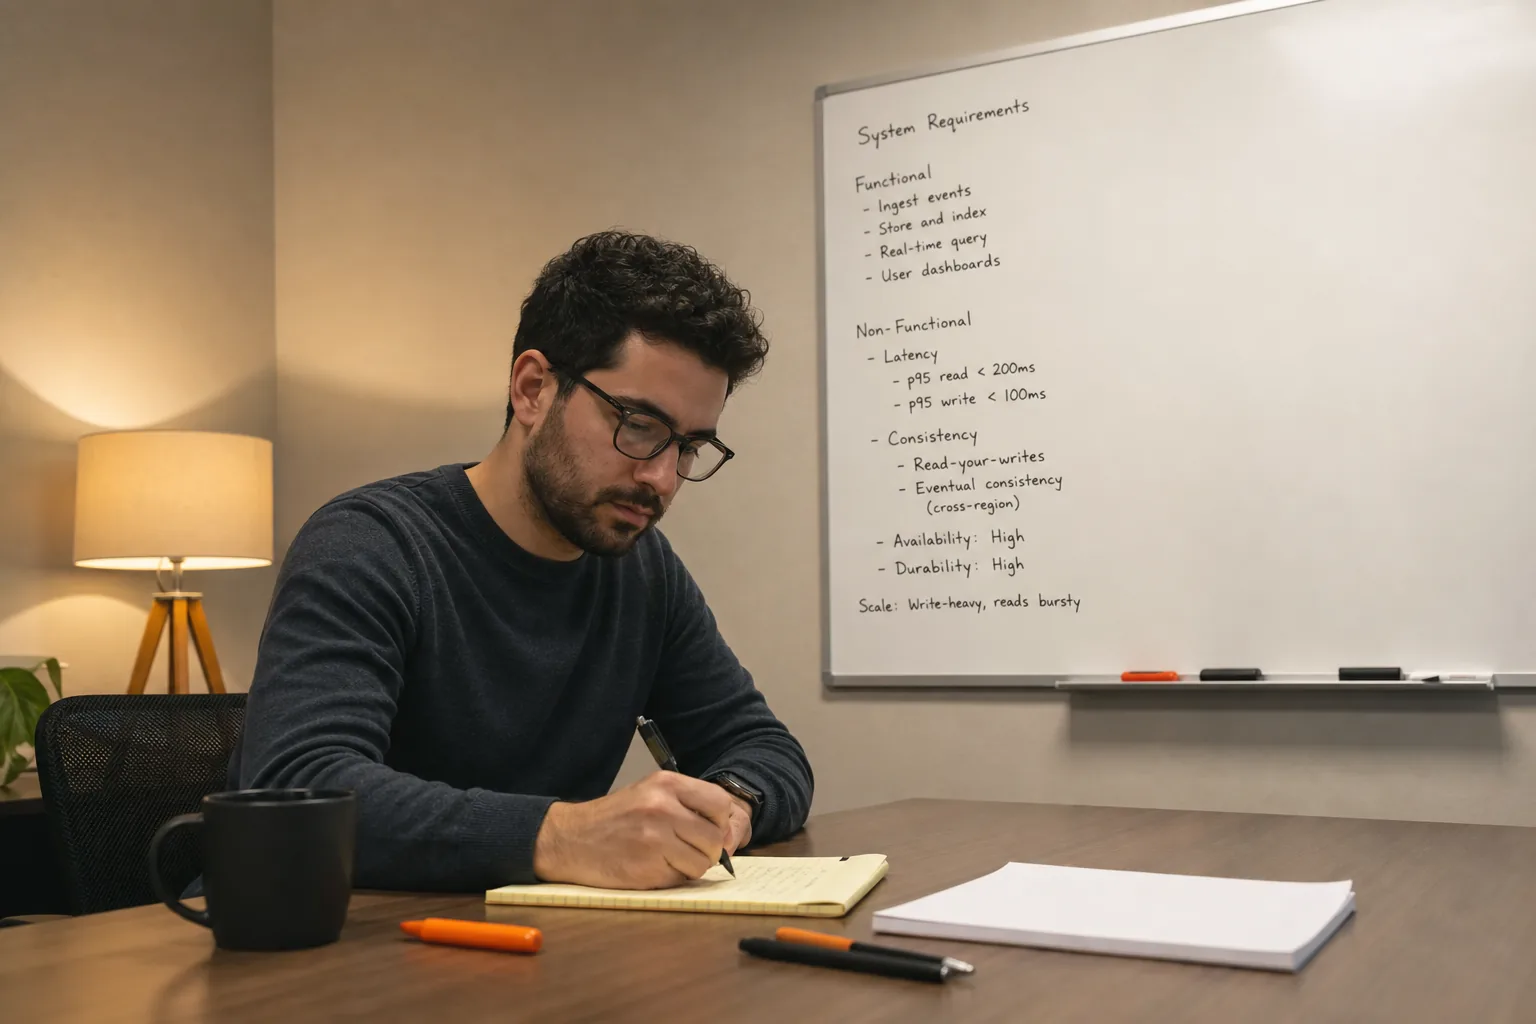
To practice whiteboard explanation for distributed systems, begin with a silent requirements drill. Your goal is to delay the diagram until you know what the system must do.
Set a timer for five minutes. Read a prompt such as “design a news feed” or “design a distributed rate limiter.” Do not draw yet. Write down the questions you would ask an interviewer:
- Who uses the system?
- What is the main read path?
- What is the main write path?
- What load should the system handle?
- What latency target matters?
- Can the system return stale data?
- What happens when a region or service fails?
Next, sort the answers into functional and nonfunctional needs. Functional needs describe actions, such as posting an event or fetching a feed. Nonfunctional needs describe limits, such as latency, durability, availability, or data freshness.
Say your assumptions out loud. “I’ll design for reads to dominate writes.” “I’ll allow eventual consistency for feed ranking.” “I’ll keep read-after-write behavior for the author.” These statements give the rest of your explanation a clear path.
This opening habit appears in several system design practice methods because drawing too early hides gaps. A useful rule is simple: if you cannot state the main access pattern, you are not ready to pick a database or shard key.
By now you should have a short scope statement, a list of core operations, and two or three measurable constraints. Only then should the marker touch the board.
Step 2: Draw the Architecture and Narrate Each Decision
The next part of whiteboard explanation practice is a repeatable drawing order. Sketch only the pieces needed to answer the prompt, then explain why each piece exists.
Start at the client. Draw the request path toward the edge, service layer, data store, and any queue or worker. Keep the first diagram small. A few clear boxes are better than a crowded board filled with services you have not explained.
As you draw each box, use a short sentence:
- “The API layer checks identity and validates the request.”
- “The queue absorbs short write spikes.”
- “Workers consume events and update the feed store.”
- “The cache handles repeated reads for hot keys.”
Then trace one write and one read. Use arrows. Name the data that moves along each path. For a feed system, a write may enter an event service, pass through a queue, and reach a fanout worker. A read may hit a cache before it reaches the feed store.
Do not treat the diagram as decoration. It is a map of your argument. If you draw a queue, say what problem it solves. If you draw a cache, state what happens after an eviction. If you draw a replica, explain which reads can go there.
Practice with a fixed speaking frame: “I’m choosing X because of Y. The cost is Z.” For example, “I’m using asynchronous fanout because feed reads need low latency. The cost is more write work and harder repair when a worker fails.” This keeps trade-offs visible.
Use the system design interview preparation guide when you need a longer framework for moving from requirements into a design discussion. But during practice, keep your first pass short. You want to build a habit you can repeat under pressure.
By now you should have a readable high-level diagram, a traced request path, and a reason for every major component. If a box has no job, erase it.
Step 3: Practice One Distributed-System Primitive at a Time
Good whiteboard explanations grow from small drills. Pick one distributed-system primitive and explain it without hiding behind a large product design.
Start with identifiers. Explain how you would make an ID unique across several writers. Discuss ordering only if the product needs it. Then move to queues. Draw a producer, a broker, and a consumer. Explain retries, duplicate delivery, acknowledgement, and a poison message.
Next, practice caches. Draw the key lookup path. State the eviction policy. Explain whether writes go through the cache or around it. Then handle a cache miss and a stampede, where many requests ask for the same missing value at once.
Rate limiting is another useful drill. Draw a token bucket and explain what the tokens represent. Then describe what changes when several application servers share the same limit. A local counter is easy to draw, but it can allow too much traffic when requests spread across hosts.
For storage, practice quorum writes and anti-entropy. Define the read count, write count, and replica count before you claim that a read is strong. Make room for delayed messages, stale replicas, and repair. The CAP theorem explanation on Wikipedia is a useful reference for the basic consistency, availability, and partition model, but interview answers need more than the slogan about choosing two items.
Use the same drill for schedulers, partitioning, replication, and backpressure. Give each topic a small card with four prompts:
- What problem does it solve?
- What is the normal request path?
- What fails first?
- What trade-off does the design accept?
Keep each explanation between three and seven minutes. Record yourself if possible. Listen for terms you use without defining. Also listen for places where you jump from a box on the board to a conclusion without tracing the request.
Once you can explain a primitive alone, place it inside a larger design. A cache should become part of a feed. A queue should carry payment events or activity updates. The point is to connect a small idea to a product need.
Step 4: Add Failure Modes, Trade-Offs, and Precise Vocabulary
Distributed-system whiteboard practice becomes much stronger when every design includes a failure pass. After your normal path works, ask what breaks when a dependency slows down or disappears.
Use a failure grid. Pick one row at a time:
| Failure | Question to answer | Decision to state |
|---|---|---|
| Cache outage | Can the database take the extra reads? | Set a fallback and protect the store. |
| Queue delay | Can the product show older data? | Expose freshness limits. |
| Replica lag | Which reads may be stale? | Route sensitive reads with care. |
| Hot partition | What key receives too much traffic? | Split or spread the hot key. |
| Worker retry storm | Can retries add more load? | Use backoff and a retry limit. |
Now make the vocabulary precise. Say “eventual consistency” when replicas may disagree for a time. Say “read-after-write” when a user must see their own update. Say “token bucket” when the limiter stores tokens that refill over time. Avoid saying “the database will be consistent” without naming the level or the read path.
Use a trade-off sentence for every major choice. “We shard by user ID because the main lookup is per user. The cost is poor range scans.” Or, “We duplicate a small user profile into the event record to avoid cross-shard joins. The cost is more storage and harder backfills.”
That second-order effect is where many explanations weaken. A shard key may make one query fast while making another query fan out across every shard. A quorum setting may reduce stale reads while increasing latency during a slow replica. A retry policy may improve recovery while causing a thundering herd.
For a deeper failure drill, use the distinction between normal behavior and repair behavior. Explain what serves traffic during the incident. Then explain how the system returns to a healthy state. Anti-entropy, read repair, backfills, and rebalancing belong in the second answer, not as vague afterthoughts.
Give yourself one minute to name the worst failure before you discuss improvements. This forces the explanation toward risk instead of adding features for their own sake.
By now you should be able to name the main guarantee, the first likely failure, and the cost of your chosen fix. That is a stronger answer than a diagram with ten services.
Step 5: Run Timed Mock Explanations on Unseen Problems
Finish your practice with unseen prompts. The goal is to explain a system when you cannot recall a prepared answer word for word.
Choose a prompt you have not studied. Set a timer for 35 to 45 minutes. Use this sequence:
- Spend the first five minutes on requirements and scope.
- Spend the next ten minutes on the high-level design.
- Trace one write path and one read path.
- Spend ten minutes on scale, storage, and bottlenecks.
- Use the final minutes for failures and follow-up questions.
Ask a friend to interrupt you with changes. Increase traffic. Remove a region. Require read-after-write behavior. Add a hot customer or a burst of writes. If you practice alone, write these changes on cards and reveal them after your first design pass.
Score the session with a short checklist:
- Did you ask questions before drawing?
- Did you state assumptions?
- Did you explain each major box?
- Did you trace both directions of traffic?
- Did you name a bottleneck?
- Did you explain recovery after failure?
- Did you answer follow-ups without abandoning the original goal?
Phantom Code AI can fit into this stage as a practice partner. It listens during mock or live technical interviews, transcribes the exchange, recognizes problem types, and provides real-time guidance. That can help when you need feedback on your explanation while the session is still moving, rather than only after you finish reviewing a recording.
Use that feedback to find one behavior to change in the next session. Maybe you draw before clarifying scope. Maybe you name a cache without explaining invalidation. Maybe you spend too long on internals before stating the product requirement. Fix one pattern at a time.
Repeat the same prompt later only after you have practiced an unseen one. Familiar prompts test memory. New prompts test reasoning. You need both, but reasoning deserves the harder workout.
FAQ
How long should I practice whiteboard explanations for distributed systems?
Practice for 30 to 45 minutes per session, then review one behavior. Spend the first five minutes on requirements rather than drawing. A shorter session works if it includes a full explanation, a failure pass, and a quick self-review. Daily repetition helps build fluency, but the quality of the feedback matters more than filling a calendar.
What should I draw first in a distributed systems interview?
Draw after you clarify the main requirements and constraints. Start with the client request path, then add the service, storage, queue, or cache that directly supports it. Do not begin with every possible component. The first diagram should show the core flow clearly enough that the interviewer can challenge one decision.
How do I practice distributed system failure scenarios?
Take a finished design and remove one dependency at a time. Ask what users see, which requests still work, and how the system recovers. Test cache loss, replica lag, queue delay, hot partitions, and retry storms. State both the immediate fallback and the repair plan. This turns failure practice into a repeatable whiteboard drill.
Can AI help me practice system design interviews?
AI can help by giving feedback during a mock session, especially when you need to improve your speaking flow. Phantom Code AI listens, transcribes, recognizes interview problem types, and provides real-time guidance. Use it as a feedback aid, not as a replacement for learning consistency, partitioning, queues, storage, and failure trade-offs.
How can I stop drawing too early?
Set a five-minute no-drawing rule at the start of each practice prompt. Use that time to ask about users, traffic, latency, freshness, durability, and failure limits. Write only words. When the timer ends, state your scope in two sentences before drawing. This makes requirements gathering a habit rather than a reminder you forget under pressure.
Conclusion
Practice the opening first: ask questions, state assumptions, and delay the diagram until the scope is clear. Then run one timed explanation each week with an unseen prompt, a failure pass, and one behavior to fix. If you want feedback while you speak, try Phantom Code AI during a mock system design session and use the result to shape your next drill.