How Enterprise Teams Choose Mock Interview Solutions
Learn how enterprise teams choose mock interview solutions by matching practice to roles, piloting feedback, and checking privacy, fairness, and fit.
Mock interview practice can miss the mark when it tests the wrong skills or gives feedback no one can act on. To choose well, map practice to each role, test tools against the same rubric, then check how they handle privacy and rollout.
We read the privacy policies of five mock interview platforms, Yoodli, Big Interview, interviewing.io, Karat, and HackerRank, for stated retention windows and accessibility disclosures. Only one, Yoodli, names an exact deletion window, 1, 7, or 30 days, limited to its advanced or enterprise plans. Two of the five, Karat and HackerRank, reference accessibility accommodations, while Yoodli, Big Interview, and interviewing.io do not mention accessibility at all. That gap shows why checking retention and accessibility details directly with each vendor matters more than trusting a feature page.
Table of Contents
- Step 1: Define the roles, skills, and interview gaps to address
- Step 2: Match the practice format to the interview skill
- Step 3: Pilot the shortlist with a consistent evaluation rubric
- Step 4: Check privacy, accessibility, policy, and rollout requirements
- FAQ
- Conclusion
Step 1: Define the roles, skills, and interview gaps to address
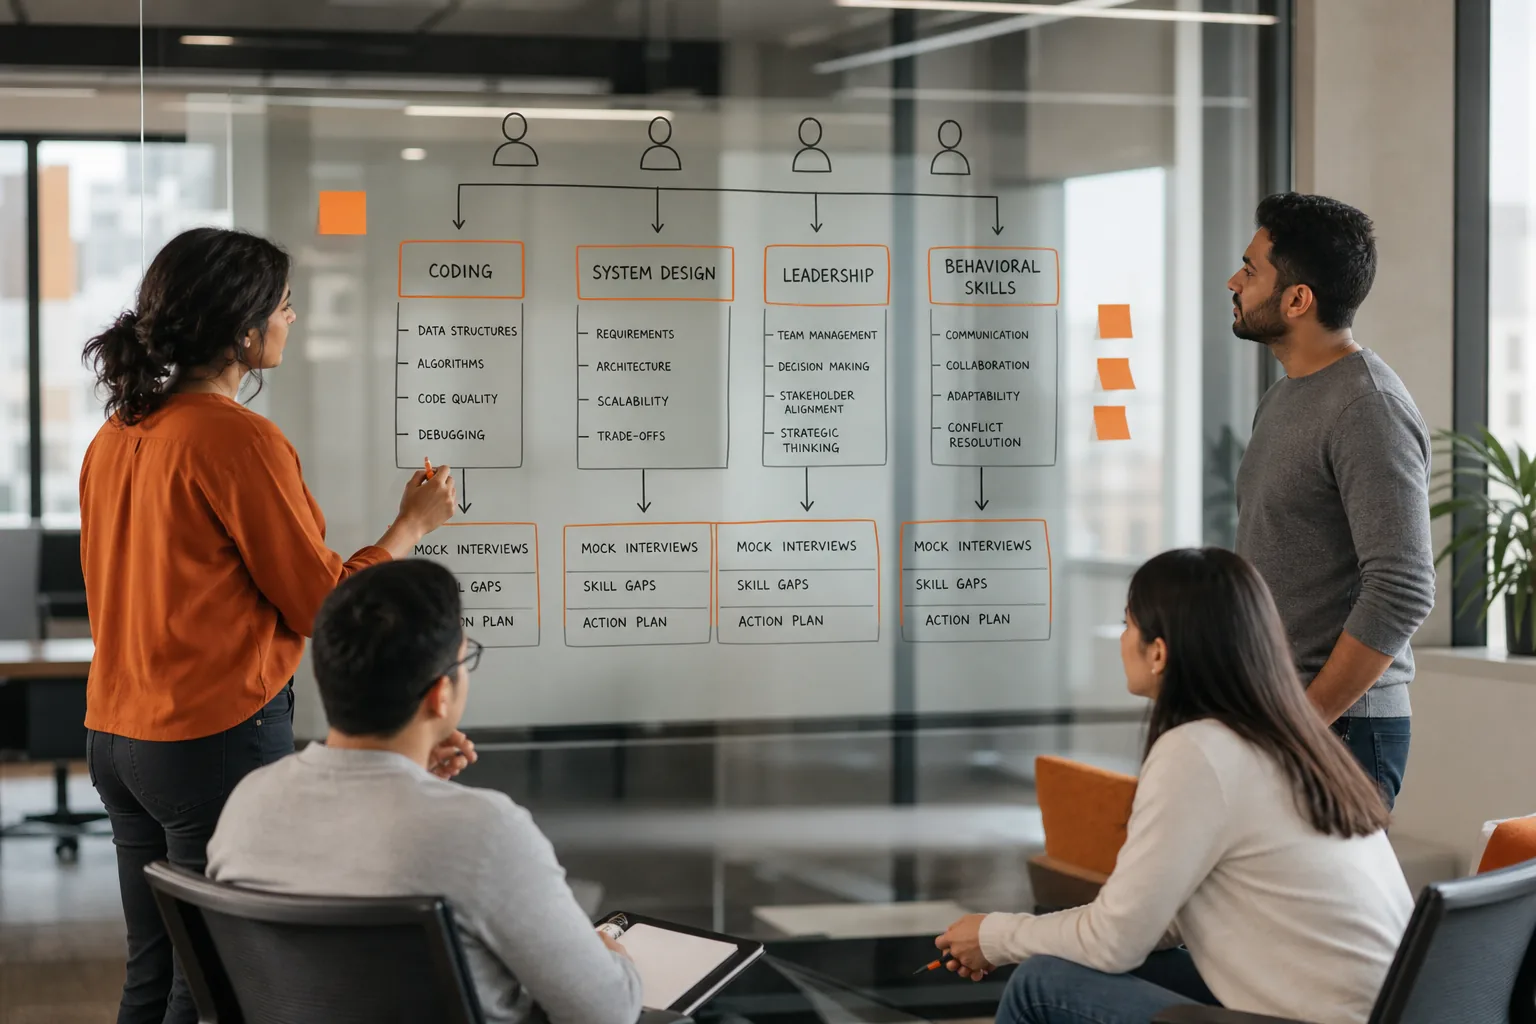
Start by listing the roles and interview rounds your team wants people to practice. An enterprise engineering group might need separate paths for backend coding, system design, behavioral interviews, and internal promotions. A single generic question set won't show whether each path tests the skills the role needs.
For each path, name the skill and the gap you want practice to reveal. For a data structures and algorithms round, that might be stating a solution's time complexity or catching an edge case. For system design, it could be explaining a trade-off between consistency and availability. For a behavioral round, the issue might be giving a vague answer that hides the candidate's own contribution.
Include leadership, management, internal mobility, and company-specific questions where they fit the roles. A future team lead may need to answer, “How would you handle conflict between engineers?” A manager may be asked, “How would you respond if a team member missed the same target twice?” Someone applying internally might face, “Why do you want to move to this team?” Company-specific practice can ask, “Which part of our engineering principles would shape your first design decision?”
For every question, write down what a useful answer should show. A leadership response should explain how the candidate helped the team meet a shared goal. A company-specific answer should connect the candidate’s choice to a known product or business need, not repeat a broad claim about being excited to work there. Ask for the action taken, the reason behind it, and the result. That structure helps keep feedback focused on impact and business alignment.
Keep the first scope narrow. Choose a few roles with different interview formats, then add more once you know what the feedback should measure. A set of questions to ask a hiring manager in a tech interview can also help candidates practice company-specific discussion without guessing at the team’s priorities.
Decide whether the program is for candidates preparing for external interviews, internal transfers, or interviewer training. Those are different jobs. Don’t use candidate practice results as hiring scores unless your policy clearly supports that use and the process has been reviewed for fairness.
By now, you should have role paths, sample prompts, and a short list of skills to assess. That gives the team a clear test for the formats in the next step.
Step 2: Match the practice format to the interview skill
When enterprise teams choose mock interview solutions, they should match the practice format to the skill under review. A question bank can help someone recall concepts. It won't show how they explain a decision while a person asks follow-up questions.
Use asynchronous practice for repeatable answers that benefit from replay. A candidate can record a behavioral response, review whether it explains their own actions, then try again. For speaking habits, tools such as Yoodli focus on delivery feedback like pacing and filler words. That can help someone who knows what to say but rushes through the answer.
Use a live human session when the skill depends on unscripted interaction. For example, a human interviewer can ask why an engineer chose one database design over another, then change the constraint. Peer practice can add live repetition at low cost, but feedback may vary by reviewer. Question banks such as PracHub can support study, though reading a written solution is different from explaining a solution aloud under time pressure.
For coding practice, choose a format where the candidate can explain the approach as they work. A useful session should expose whether they clarify requirements, test edge cases, and talk through complexity. For system design, the interviewer should be able to probe a changed traffic pattern or a new failure requirement. The goal isn't to collect scores. It's to find a moment the candidate can improve and test that improvement on a new prompt.
| Interview skill | Practice format to test | What to inspect | Watch-out |
|---|---|---|---|
| DSA reasoning | Timed coding session with spoken explanation | Assumptions, edge cases, complexity | A correct answer may hide unclear reasoning |
| System design | Live prompt with follow-up changes | Trade-offs and response to new constraints | A fixed script may miss adaptive thinking |
| Behavioral stories | Recorded response or interviewer-led mock | Personal actions, impact, and relevance | Generic answers can sound polished but say little |
| Speaking delivery | Recorded speech analysis | Pacing, clarity, and filler words | Delivery scores don't measure technical judgment |
Phantom Code AI is one option to test when engineers need a desktop assistant for mock interviews. It listens, transcribes, identifies problem types, and provides real-time guidance; its stated integrations include Zoom, Google Meet, and Microsoft Teams. Check that the mock setup matches your rules and learning goal. A tool's ability to assist during a session doesn't mean it is allowed in a hiring assessment.
Use a mix if one format can't cover the skill. For example, pair repeatable AI practice with a live human session before a high-stakes interview. A mock interview strategy for software engineers can help candidates set a specific practice goal instead of repeating random questions.
Step 3: Pilot the shortlist with a consistent evaluation rubric
A pilot shows whether a solution produces useful practice, not just a long feature list. Choose a small group and a few role types. Give each participant the same prompt and clear instructions, then use one rubric across tools. Keep the pilot separate from hiring decisions unless the organization has approved that use.
Build the rubric around observable actions. In a coding mock, you might note whether the candidate clarified inputs before coding, tested a boundary case, and explained the time cost of the solution. In a system design mock, record whether they identified a bottleneck and explained the trade-off behind a proposed fix. For a behavioral response, check whether the person explains their own action and connects the outcome to the role.
Keep ratings simple. A short scale can show whether a behavior was missing, emerging, or clear. Add a note with a specific example from the session so the score has context. Don't treat an automated score as a fact about a person's ability. Confirm whether its feedback points to something a coach or candidate can hear in the session.
Ask participants to try a related task after they review feedback. If a candidate learns to state an assumption in one design question, see whether they do it in a different prompt. If they revise a behavioral answer to make their own role clearer, see whether the same improvement carries into another story. This follow-up makes the pilot about learning, not about who got the highest score on one attempt.
Track operational signals too. Note how much coordinator time it takes to assign practice, whether candidates can complete sessions on their own, and whether reviewers can find the feedback they need. These observations can help estimate workload. Don't claim the tool reduced time-to-hire or improved hiring quality unless your pilot measures those outcomes against a fair comparison.
Phantom Code AI can be included in the pilot when the target skill involves coding or system design practice with real-time assistance. Test whether its transcription and problem recognition work for the prompts your team uses. Phantom Code AI's official site describes its interview assistant and practice use; verify the current product details and session conditions before you set up the test.
For another comparison point, a guide to dynamic programming interview questions can help your team select a consistent practice problem and check whether feedback addresses the candidate's reasoning.
By the end of the pilot, you should have evidence on task fit, feedback quality, completion effort, and any gaps in the workflow. Keep the notes. They will make the final review less dependent on memory or enthusiasm after a demo.
Step 4: Check privacy, accessibility, policy, and rollout requirements
Before rollout, confirm what each tool collects and how people can control it. Mock sessions may include voice, transcripts, video, code, or personal examples. Ask where those records go, who can access them, how long they're kept, and how a participant can request deletion. Don't assume a vendor's feature page answers each question.
Set a clear boundary between private preparation and an employer assessment. Candidates should know when recording is on and whether a coach or manager can view a session. They also need clear guidance on AI assistance. Practice can use tools approved for practice; a live interview or assessment follows the employer's rules. If those rules are unclear, ask before using assistance.
Review accessibility with the people who will use the system. Check whether prompts can be read as well as heard, whether keyboard-only use works, and whether captions or transcripts support people who need them. Ask participants to test the workflow with their assistive technology. A tool that works for one test user may still create barriers for another.
Fairness needs more than a vendor claim. Check whether the rubric measures job-related skills, and whether the same standards apply across participants. Speech analysis can flag pace or filler words, but those signals shouldn't stand in for technical skill or communication quality without a clear reason. Give reviewers examples of what counts as evidence, and a way to question an output that doesn't fit the session.
For a rollout, name an owner for each part of the process. Someone should maintain role prompts. Another person should handle access and participant questions. Decide where session records live and which reports managers can see. If you plan to link a tool to an ATS, LMS, or HRIS, confirm the integration exists and ask what data moves through it. Don't treat a requested integration as a current capability.
Ask vendors for written answers on data handling, access controls, retention, accessibility, and support.
Finally, set a review date after launch. Check completion, support requests, and rubric fit. If people keep skipping a step or can't use a feature, fix the workflow before you expand to more teams.
FAQ
How do enterprise teams choose mock interview solutions?
Enterprise teams choose mock interview solutions by matching each format to a role skill, then testing feedback against a shared rubric. Start with a coding, system design, or behavioral gap. Pilot the same task across shortlisted options. Before rollout, verify privacy, accessibility, and the rules for using assistance in practice versus an actual assessment.
Should a company use AI or human mock interviews?
Most teams should match the format to the skill instead of choosing only one. AI can support repeatable practice and quick feedback, while a human can ask unscripted follow-ups. For example, use AI to rehearse explaining a coding approach, then ask an experienced engineer to challenge the design assumptions in a live mock.
What should an enterprise mock interview rubric measure?
A rubric should measure behaviors tied to the role, such as how a candidate states assumptions, tests edge cases, explains trade-offs, or describes their own impact. Keep evidence separate from impressions. For each rating, add a brief note from the session so candidates and reviewers can understand what to change next.
What should teams check before using interview practice software?
Teams should check what data the software records, who can access it, and how long it is retained. They should also test accessibility and confirm whether the tool fits their interview policy. A mock interview is preparation; assistance during a live hiring assessment needs clear permission from the employer.
Conclusion
Choose the tool that helps people improve a defined interview skill, then confirm the workflow meets your privacy and policy needs. Start with one role and a shared pilot rubric. If your engineers need guided coding or system design practice, consider testing Phantom Code AI in that pilot, alongside a live human session where useful. Teams can book a one-to-one mock interview with a senior engineer as a next step.