How to Practice Database Sharding Scenarios
Learn how to practice database scaling and sharding scenarios with workload models, shard-key drills, failure tests, and interview-ready tradeoffs.
Database scaling questions get hard when the prompt stays vague. You need a workload, a baseline, and a clear reason for each design choice. Use the steps below to practice the full decision path.
Table of Contents
- Step 1: Turn a Scaling Prompt Into a Concrete Workload
- Step 2: Build and Measure a Single-Database Baseline
- Step 3: Choose a Scaling Path Before Introducing Shards
- Step 4: Design the Shard Key, Routing, and Rebalancing Plan
- Step 5: Run Failure, Consistency, and Capacity Drills
- FAQ: Database Scaling and Sharding Practice
- Conclusion
Step 1: Turn a Scaling Prompt Into a Concrete Workload
The first step in learning how to practice database scaling and sharding scenarios is to turn broad growth claims into numbers and access patterns.
Take a prompt such as, “Design a platform that stores user events.” Rewrite it as a short workload sheet. State the number of users, the write rate, the read rate, the largest record, and the retention period. Add the traffic pattern. Is demand steady, or does it spike during a launch?
Then list the main requests. For example:
- Write an event for one user.
- Fetch a user’s recent events.
- Find events within a time range.
- Run a daily count by account.
For each request, mark its latency goal and its consistency need. A user profile update may need a fresh read. An analytics count may tolerate delay. This split gives you a reason to consider replicas, a queue, or a separate reporting store before you reach for shards.
Keep the first exercise small. Suppose you model a defined user population, a write rate, and a read path keyed by user ID. The exact values are less important than the assumptions. During an interview, say which values are estimates and how you would revise the design if traffic doubled.
Also write down what the system must not do. A query that scans every user’s events will become a problem even if the database has spare CPU. A request that joins data across every tenant may force scatter-gather work later.
Step 2: Build and Measure a Single-Database Baseline
Before you practice sharding, measure the same workload on one database. Otherwise, you can't tell what the shards fixed.
Build a small schema that matches the access paths from Step 1. Add an index for the main lookup. Load enough rows to expose query cost, but don't pretend a tiny test proves production capacity. Your goal is to compare designs under the same load.
Measure each request on its own. Record throughput, median latency, tail latency, CPU use, memory use, storage growth, and connection count. Averages can hide a slow group of requests, so watch the slowest samples as the load rises.
Run the test in stages. Start below the expected rate. Increase clients until latency rises sharply or errors appear. Keep the data mix fixed. If you change the query, index, and client count at once, you won't know which change caused the result.
Next, test the common fixes that come before sharding:
- Add or adjust an index for the dominant filter.
- Read from a replica when stale data is acceptable.
- Cache a result with a clear expiry rule.
- Move slow work into an async job.
Write down the limit of each fix. A read replica won't solve a write bottleneck. A cache helps when requests reuse stored results before they expire. If each key is requested only once, the cache may add overhead without avoiding database work, as the Microsoft cache-aside guidance explains. This explanation matters in interviews because sharding adds a large operating cost.
Phantom Code AI can help you rehearse this explanation in a mock system design round. Practice saying what you measured, what failed first, and why the next change is justified. The goal is a spoken chain of decisions, not a list of database terms.
By now you should have a workload sheet, a repeatable test, and a baseline that shows the first real limit.
Step 3: Choose a Scaling Path Before Introducing Shards
Scaling practice works better when you compare options before declaring that the database needs shards.
Use the baseline to ask what is full. If one query is slow, fix the query. If reads dominate, test caching or replicas. If one machine cannot handle the write rate or data size, then horizontal scaling deserves serious attention.
Cloud products expose different levels of control. TiDB describes automatic sharding across nodes. Oracle Database Sharding describes built-in horizontal scaling. Those choices lead to different interview answers because they change how much routing work your application owns.
Other systems hide more of the decision. Elastic Cloud Serverless manages sharding and does not let the user configure it. That can simplify operations, but it gives you less practice with shard-key mistakes. Its documented scaling exercise centers on adding concurrent indexing clients instead.
| Situation in your baseline | First path to test | What to explain in an interview |
|---|---|---|
| Reads are slow, writes are moderate | Index, cache, or read replica | Why stale reads are safe for this request |
| One write node is saturated | Write partitioning or sharding | How the key spreads writes |
| Data size is the main limit | Partitioning, archival, or sharding | How old data leaves the hot path |
| One tenant dominates traffic | Tenant-aware placement | How you prevent a hot tenant shard |
| Reporting scans hurt user traffic | Async pipeline or separate store | Why analytics should not share the request path |
Compare the operational cost of each scaling path before choosing one.
For interview drills, Phantom Code AI is useful when you need follow-up pressure. Ask it to challenge the choice: “Why isn't a read replica enough?” Then answer with the measured limit from your baseline.
Step 4: Design the Shard Key, Routing, and Rebalancing Plan
Now practice the part that usually decides whether a sharded design works: map each request to the right shard.
Start with the query pattern, not the column list. If most requests includeuser_id, that field may support targeted reads. If most requests filter by time, a time range may fit the workload, but new writes can pile onto the newest range.
Test each candidate key against four questions:
- Does it have enough distinct values to spread rows?
- Does traffic spread across those values?
- Do common requests include the full key?
- Can related updates stay on one shard?
Then make the routing rule explicit. A request with the shard key should reach one shard. A request without it may need scatter-gather work, where many shards run the query and one layer merges the results. Say what happens to latency when that occurs.
Try a tenant example. A key such as(tenant_id, entity_id)may keep most tenant work together. But a query that knows onlyentity_idmay lose targeted routing. This is the tradeoff you want to explain out loud.
Plan for a hotspot drill. Put most writes under one tenant or one popular key. Watch shard-level load, not only the cluster total. A cluster can look healthy while one shard throttles requests.
Next, explain rebalancing. State how you add a shard, move ranges or key groups, keep writes available, and verify that no rows are lost. A good answer names the migration risk. Moving data can compete with normal traffic and can make latency worse before it gets better.
Database sharding means splitting a logical dataset across database systems, while partitioning usually keeps the split inside one system. That distinction is useful when you explain why the operational work changes after sharding. The database sharding distinction is also useful when you explain shard keys, targeted queries, hotspots, and cross-shard work.
Product-specific designs can use user-selected shard keys for Aurora Limitless Database and automatic sharding for TiDB. Treat those as product-specific designs, not universal rules.
Finish this step with a one-page design. Include the key, the routing function, the query paths that scatter, the hotspot response, and the rebalancing plan.
Step 5: Run Failure, Consistency, and Capacity Drills
The last step in how to practice database scaling and sharding scenarios is to break the design on purpose.
Run one drill at a time. First, make one shard unavailable. Describe what the client sees, how retries behave, and whether another copy can serve the request. Then make the network slow between the router and a shard. This tests timeouts and retry storms.
Run a consistency drill next. Write a profile update, then read it through a path that may use a replica. Decide whether the user must see the new value at once. If the answer is yes, route that read to the leader or use a read-after-write rule. If the answer is no, state the accepted delay.
Test cross-shard actions with an order example. Suppose an order update changes inventory on one shard and a payment record on another. Ask what happens after the first write succeeds and the second fails. A strong answer may use an outbox or saga-style workflow instead of pretending that every distributed transaction is free.
Capacity drills should change one pressure at a time. Raise write concurrency. Then raise read concurrency. Then add a hot key. Finally, grow the data set while keeping traffic steady. Watch whether the problem is CPU, storage, locks, connection limits, or network delay.
Keep a failure log with five fields:
- Trigger: what changed.
- Symptom: what users saw.
- Scope: one shard or the whole service.
- Recovery: what action restored service.
- Tradeoff: what new cost the fix introduced.
This format turns a test into interview practice. It also stops you from claiming that sharding fixes every problem. A bad key can add more failure points while leaving the hot path unchanged.
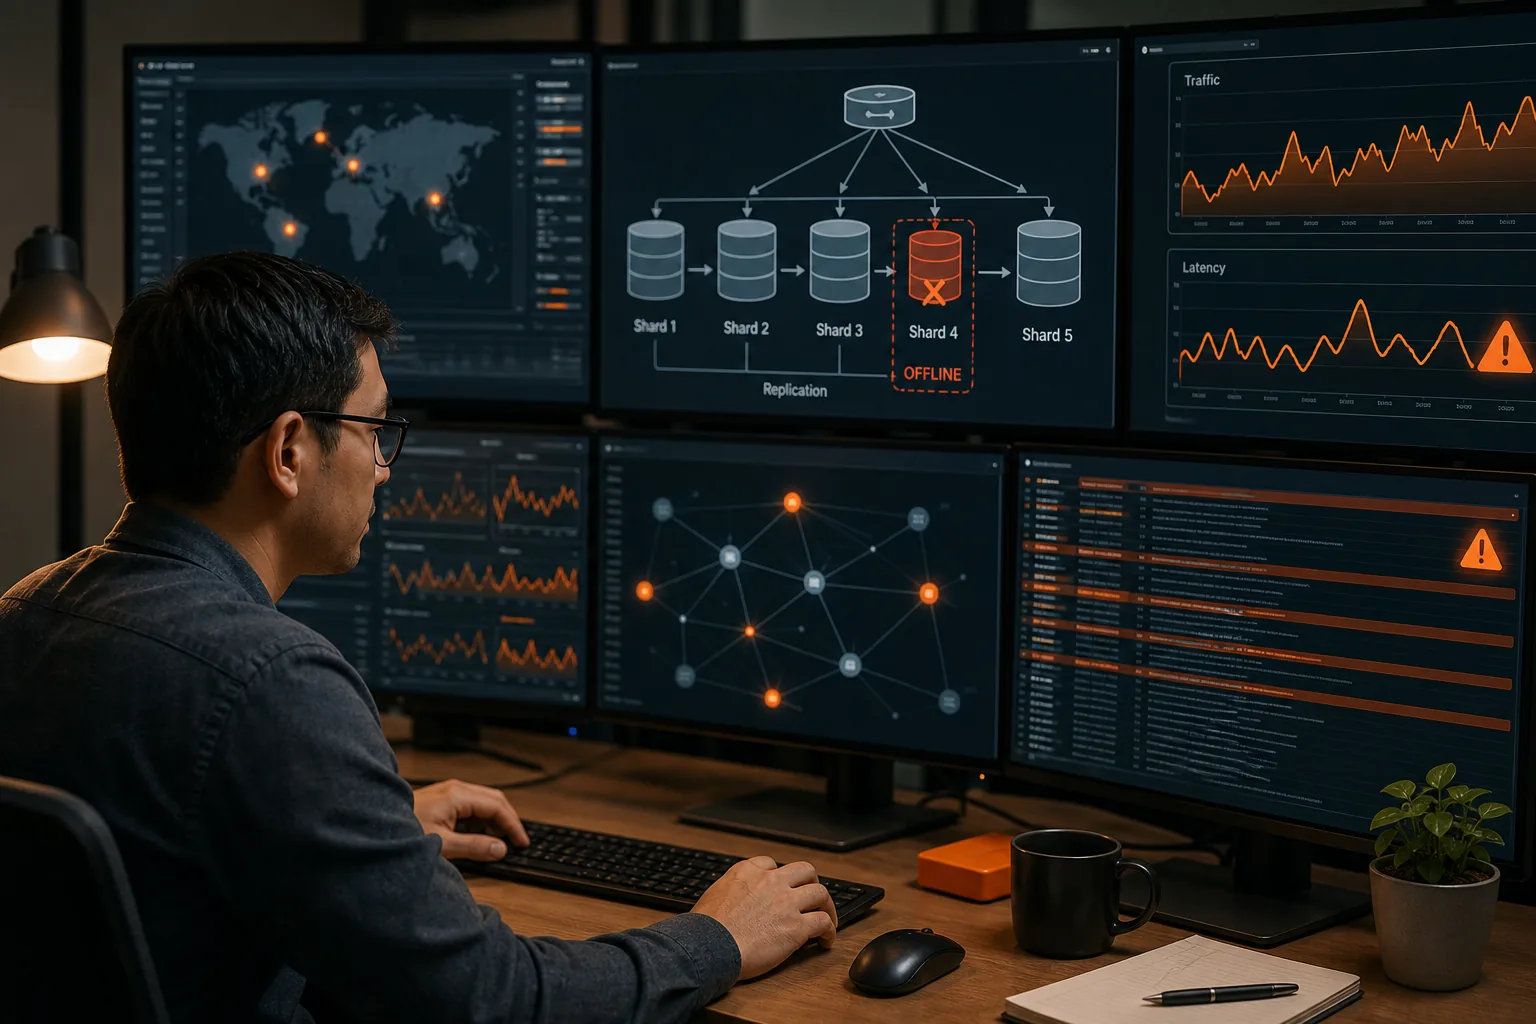
For a spoken mock round, ask Phantom Code AI to interrupt with follow-ups such as, “What if the shard key becomes hot?” or, “How do you roll back a partial migration?” Answer in order: impact, containment, recovery, and long-term fix.
When the drill ends, compare the result with your original baseline. If the design cannot show a clear gain or a clear capacity reason, keep the single database and explain why.
FAQ: Database Scaling and Sharding Practice
How do I practice database scaling without a cloud budget?
You can practice database scaling with a local database, a small generated data set, and a repeatable load script. Focus on query plans, connection pressure, indexes, and routing logic.
What metrics matter before sharding a database?
Measure throughput, tail latency, CPU, memory, storage, connection count, and error rate before sharding. Split results by request type and watch each shard or node separately once you distribute the workload. A baseline lets you show whether sharding solved a write limit, a storage limit, or neither.
How do I choose a shard key in a system design interview?
Choose a shard key from the most common query paths. Check its cardinality, traffic spread, hotspot risk, and ability to keep related writes together. Then name the queries that lack the key, because those may scatter across shards and weaken the design.
Is sharding always better than replication?
No, sharding is not always better than replication. Replication can help when reads are the problem and the data still fits within one write node. Sharding adds routing, rebalancing, cross-shard queries, and more failure cases, so use it only after simpler changes fail to meet the workload.
How can I practice answering database follow-up questions?
Practice each answer in four parts: state the bottleneck, name the design change, describe the tradeoff, and explain the failure plan. Phantom Code AI can provide live guidance during mock technical interviews, but you should still verify every answer against your own workload model and test notes.
Conclusion
Start with a single-database baseline, then add sharding only when the measured workload demands it. Your next action is simple: write one workload sheet tonight, run one baseline test, and explain the first scaling limit aloud. That habit will prepare you for far more follow-up questions than memorizing database product names.