Database Sharding Explained: Core Concepts
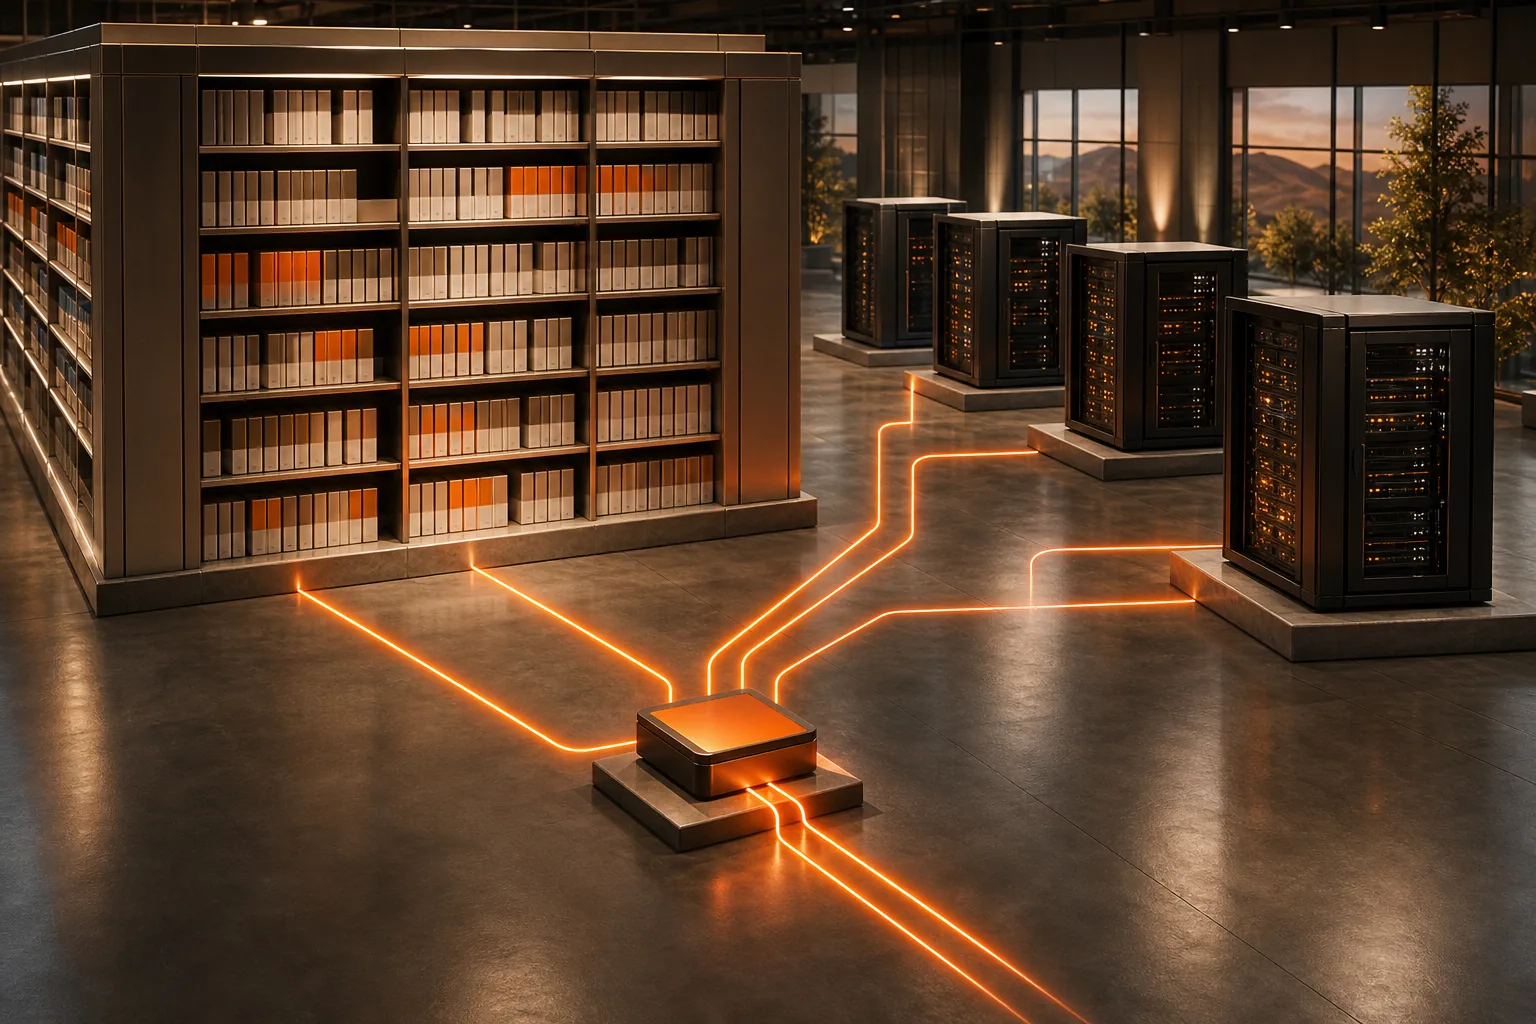
Database sharding explained: see how shards split data, how keys route queries, and what trade-offs to weigh before scaling a database.
Database sharding explained simply: it splits one logical database into smaller databases that run on separate machines. Each shard holds part of the data, so the system can spread storage and work across more machines. The hard part is choosing what goes where, then keeping queries and operations manageable.
We analyzed 5 sharding explainers about database sharding and found that 0 of 5 name scatter-gather queries and only 1 covers cross-shard transactions. Just 2 of the 5 mention consistent hashing.
We analyzed 5 sharding explainers (Akamai, DesignGurus, DataCamp and 2 DEV Community posts) about database sharding and found that 0 of 5 name scatter-gather queries and only 1 covers cross-shard transactions. Just 2 of the 5 mention consistent hashing.
Table of Contents
- What Database Sharding Is and How It Distributes Data
- Shard Keys, Routing, and Common Partitioning Approaches
- Sharding Trade-Offs: Cross-Shard Queries and Rebalancing
- When Sharding Makes Sense in a System Design
- Frequently Asked Questions
- Conclusion
What Database Sharding Is and How It Distributes Data
A shard is a database that holds a distinct slice of a larger dataset. The shards share a schema, but each runs on its own node with its own processing, memory, and storage. Together, they act like one logical database to the application.
This design is called horizontal scaling. Instead of making one server bigger, the system adds servers and splits rows among them. That differs from vertical scaling, which adds resources such as memory or CPU to a single server. Vertical scaling can help for a time, but one machine still has a limit.
In a sharded design, each database holds a distinct subset of the data while keeping the same schema.
Think of an online shop with customer and order records. If every record sits on one database server, that server must handle all storage and database work. With sharding, an order can be assigned to one shard based on a chosen key, such as the customer ID. A router reads that key and sends the request to the shard that owns the record.
Sharding can help when a single server runs short on storage or can’t keep up with query and write load. It can also reduce contention by spreading requests across machines. Replication is often added for fault tolerance, but it solves a different problem: replicas keep copies of data, while shards divide ownership of the data. Replication does not, by itself, spread write load across independent data slices.
Availability isn’t automatic. If a shard fails and no usable replica exists, the data on that shard may be unavailable. The application also needs a way to locate the right shard and handle failures along the request path.
Shard Keys, Routing, and Common Partitioning Approaches
The shard key is the field, or group of fields, that decides where each record lives. It also shapes the request path. When a query includes the key, a router can send it to the relevant shard. Without it, the system may need to ask many shards and merge their replies.
A useful key should have many distinct values and spread both data and activity across shards. It should also match common queries. For example, if an app usually fetches a customer’s orders together, a customer ID can keep those records on one shard. But a single very active customer can create a hot shard if all of that customer’s writes go to one place.
High cardinality alone doesn’t make a key good. A sequential timestamp may have many values, yet range-based placement can send every new write to the shard holding the newest time range. That leaves older shards less busy. Before choosing a key, ask whether it spreads the workload and whether common requests can use it to find one shard.
There are several ways to assign records:
- Range-based: Place nearby key values together. This suits range reads, such as retrieving orders from a given month. A steadily increasing key can concentrate new writes on one shard.
- Hash-based: Apply a hash function to a key to spread values across shards. It can balance placement, but nearby values end up apart, so range queries may need to contact many shards.
- Directory-based: Use a mapping service or table to look up the shard for a key. This can make moves flexible, but the mapping layer needs high availability and careful operation.
- Geo-based: Assign data by region when user location or data-residency rules matter. The system must still handle requests and analysis that cross regions.
- Vertical partitioning: Separate different columns or kinds of data. This is not the same as sharding rows across machines, though systems may use both approaches.
Consistent hashing can limit how much data moves when shards are added or removed. A basic hash modulo the shard count can require broad remapping when that count changes.
Directory-based placement trades automatic simplicity for control. A mapping layer can help move a large tenant without changing its key, but it becomes another service to monitor and protect. Geo placement has a similar trade: nearby storage can reduce request distance, while cross-region queries add coordination.
Sharding Trade-Offs: Cross-Shard Queries and Rebalancing
Sharding can raise storage and write capacity by spreading work, but it adds operational work. Engineers must track shard health, manage routing, plan capacity, and respond when one shard gets more data or traffic than the rest. A bigger cluster also means more machines and more parts that can fail.
Cross-shard queries are a frequent source of complexity. If a request doesn’t identify one shard, the router may send it to several shards, wait for their responses, then combine the results. This is often called scatter-gather. It adds network work and can make sorting, pagination, and joins harder.
The shard key is the most important decision: a poor choice can create hot spots and defeat the purpose of sharding.
Rebalancing is the work of moving data or load when shards become uneven, or when the system changes size. Plan for it before launch. If a shard fills up or a tenant’s traffic grows, adding a node won’t fix the imbalance unless the routing map and data placement can change too.
During a migration, teams still need to copy data, keep new writes in sync during the move, check that the destination is current, and then switch reads. Each step needs monitoring and a rollback plan.
Transactions also need thought. A write that touches records on one shard can follow that shard’s local transaction rules. A transaction across multiple shards needs coordination, which can raise latency and failure complexity. Where possible, design common operations so the related records live together. For broader reporting, a separate analytics path may be a better fit than making every live query fan out.
Watch for hot spots, uneven shard sizes, rising query fan-out, and slow shard response times. Those signals can reveal a bad key or a workload that has changed. A system that looks balanced by row count may still be uneven by request volume.
When Sharding Makes Sense in a System Design
Sharding makes sense when a database is constrained by write capacity or storage, and less complex fixes no longer meet the workload. It’s rarely the first move. First check query plans and indexes. For read-heavy traffic, read replicas may help. Caching can reduce repeated reads. Vertical scaling can also buy time if one server still has room to grow.
Those choices don’t solve every limit. Read replicas still need to receive writes, and they hold copies rather than splitting the dataset. If the main problem is write throughput or total data size, sharding may be the next option. State the bottleneck before proposing it in a system design discussion.
Then show how the access pattern guides the key. For a service where most reads and writes are scoped to one customer, a customer key may keep that path local. For time-based analytics, a range can make date scans easier, but new writes may pile up at the newest range. Name the benefit and the cost in the same answer.
For an interview, explain how you’d detect trouble and what you’d do next. Mention per-shard storage and request load, query fan-out, and latency differences. Then describe how you’d move data if one shard became a hot spot. Avoid claiming that adding nodes automatically fixes a skewed key.
Security needs a place in the design too. Shards can help isolate tenants when placement follows a tenant key, but the application still has to enforce access rules on every request. Routing mistakes can expose the wrong data, so test tenant boundaries and protect the mapping layer.
Cost planning should include more than server count. Account for replicas, monitoring, network traffic, backups, and the engineering time needed for routing and migration. Sharding may let the database grow by adding nodes, but operating several database nodes adds work that a single instance doesn’t have.
For interview prep, database sharding scenario practice can help you rehearse key selection, workload assumptions, and failure cases. Phantom Code AI is an AI interview assistant for mock or live technical interviews, including system design. Use it to practice stating the trade-off clearly, then review whether your answer ties the shard key to actual query patterns.
A strong answer usually covers four decisions: why the current database is constrained, what key matches the workload, how requests find their shard, and how the system will rebalance. Phantom Code AI can support interview practice, but the design still needs a clear explanation of its failure modes.
Frequently Asked Questions
What is database sharding in simple terms?
Database sharding splits one logical dataset across multiple database servers. Each server stores only part of the rows, and a shard key helps route requests to the right part. This can add storage and write capacity, but it also makes query routing and operations more involved.
What is the difference between sharding and replication?
Sharding divides data among database nodes, while replication keeps copies of data on more than one node. Sharding can spread storage and write work. Replication can support failover or read capacity, depending on the setup. A system may use both, but one does not replace the other.
How do I choose a shard key?
Choose a key that distributes data and request load, and that appears in common queries. Check for skew: a key with many values can still send most traffic to a few shards. Also test the key against the busiest entity and the queries that may need to reach multiple shards.
When should a database be sharded?
Consider sharding when storage or write demands exceed what a single server can handle after tuning and simpler scaling options. Read replicas can help with read load, while sharding splits data across nodes. Plan for routing, monitoring, and rebalancing before you make the change.
What are the main problems with sharding?
The main problems are hot spots, cross-shard queries, and added operational complexity. A poor key can leave some shards overloaded while others sit idle. Queries that touch many shards need extra network work, and rebalancing requires careful data movement while the system remains in use.
Conclusion
Use sharding when measured storage or write limits call for it, not as a default design choice. Before committing, map your common queries to a candidate key and test for hot spots. For interview practice, rehearse the key choice and its trade-off in one clear answer.